TL;DR
We built a multi-agent system that lives inside a client's existing Ruby backend and turns legal requirements into developer language, then assembles the evidence to back it up. We call it the Evidence Detective: a pipeline of specialized agents that finds proof of compliance in a codebase and its documentation, and hands a reviewer a sourced, quoted answer instead of a list of links.
- Time to evidence pack: ~40 hours → 3-4 hours
- Cost per audit: ~$2,000 → $100-150
- Accuracy: ~90%, based on independent spot-checks
- Annual savings: over $500,000 at roughly 300 audits a year
The system doesn't hand back links. It hands back quotes, sources, and confidence scores, ready for a legal reviewer to act on, and anything it isn't sure about goes to a person before it ships.
The real problem was proof, not links
Auditors rarely fail because the information doesn't exist somewhere. They fail because finding defensible proof of it takes forever.
A typical compliance or patent review means digging through documentation, repositories, release notes, and technical guides to answer one question: is this company actually doing what its legal documents claim? That answer can't be a link. Legal reviewers need evidence tied to a specific requirement, with the exact passage and source attached, because a link without a quote is something a reviewer has to go re-verify themselves.
The deeper issue is that legal language and implementation language rarely line up. A legal requirement might read "the system determines cryptographic key exchange status." The engineering docs never say that. They say TLS negotiation, SSL handshake, certificate validation, HTTPS configuration. A person can bridge that gap without thinking twice about it. A search bar can't. So reviewers were spending around 40 hours per audit doing that translation by hand, one requirement at a time.
Why this isn't really a search problem
It looks like one at first glance. It's actually a translation problem, and it breaks traditional search in three specific ways:
- The vocabulary gap: legal phrasing rarely matches the language engineers or documentation actually use.
- The precision gap: finding a keyword mentioned somewhere doesn't prove a specific requirement is met.
- The traceability gap: a link without a quote or surrounding context pushes the verification work back onto the reviewer instead of removing it.
What auditors actually need is something that translates the requirement, searches broadly across the sources that matter, pulls out the passages that genuinely support it, and puts the whole case together in a form legal can use immediately.
How the Evidence Detective works
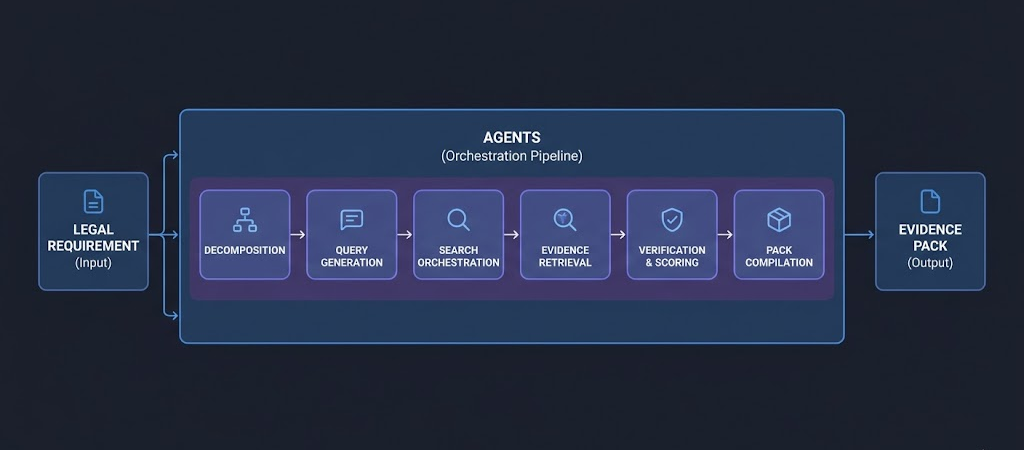
We embedded a multi-agent workflow directly into the client's existing Ruby application, no migration, no new platform, nothing rebuilt from scratch. It runs as six specialized agents rather than one large model handling everything, and that split is deliberate: a model asked to decompose a legal requirement, search the web, extract a quote, and score its own confidence all in one pass tends to blur those steps together. Splitting them into a pipeline, each agent doing one job and handing off clean, structured output to the next, is what makes the result both fast and something you can actually trust.
Agent: Element Decomposition
What it does: Breaks a legal requirement into atomic, testable elements so the system answers one narrow question at a time
Agent: Query Generation
What it does: Turns each element into 10-15 phrasings an engineer would actually use, bridging the legal-to-technical vocabulary gap
Agent: Search Orchestration
What it does: Runs those searches in parallel across documentation, repositories, release notes, and developer guides, then filters out noise
Agent: Evidence Mapping
What it does: Attaches the exact quote, source, and timestamp behind each supporting passage, nothing vague gets through
Agent: Confidence Scoring
What it does: Flags gaps, contradictions, or weak sources, and routes anything uncertain to a human instead of guessing past it
Agent: Report Generation
What it does: Assembles the final pack: requirement, quote, source, and confidence score, side by side
A concrete example
Take the requirement "the system determines cryptographic key exchange status." The Query Generation Agent expands it into TLS handshake, SSL negotiation, certificate verification, HTTPS configuration. The search agents surface a documentation passage: "During the TLS handshake, the server negotiates encryption parameters before establishing the secure connection." The Evidence Mapping Agent ties that passage to the requirement and attaches the source.
The final report looks like this:
Requirement: Cryptographic key exchange status
Evidence Quote: "During the TLS handshake, the server negotiates encryption parameters before establishing the secure connection."
Source: docs.example.com/security/protocols/tls
Confidence: 92%
Instead of hours of searching, reviewers get direct, traceable proof, in text an answer engine or a search crawler can read directly, not locked inside a screenshot.
Why Ruby helped instead of getting in the way
The whole thing runs inside the client's existing Rails stack. The agents execute as ordinary Sidekiq background jobs, and every stage talks to the next through strict JSON contracts, so there was no migration, no new platform to learn, full audit logs from day one, and read-only, least-privilege access to every source it touches. From the outside, it behaves like any other service already living in that application.
What it added up to
Time for the evidence pack went from about 40 hours to 3-4. Cost per audit dropped from roughly $2,000 to somewhere between $100 and $150. Accuracy held around 90% on independent spot-checks, and at roughly 300 audits a year, that's over half a million dollars in annual savings. More importantly, the people doing the reviewing spend their time on the parts that actually need a human, the edge cases and the legal judgment calls, instead of the hours of manual cross-referencing that used to eat the whole process.
Three things made it work, and none of them are specific to audits. Specialized agents beat a single model trying to do everything at once, because splitting the reasoning into stages is what makes each stage checkable. Evidence beats a link every time, because a link still leaves the reviewer doing the work the system was supposed to do. And the patterns the system learns on one audit carry over and make the next one faster, the same compounding effect that shows up whenever we build a system on top of a client's actual operational context instead of starting from a blank prompt.
If you want to try this on your own workflow
Start small. Pick one high-volume audit or review process, define what "proof" actually needs to look like for it, connect the read-only sources it should search, and run the system in shadow mode alongside whatever your team does today. Compare time, cost, and accuracy against that baseline before changing anything. If it doesn't outperform the current process, you'll still walk away knowing exactly where the workflow breaks down, which is most of what an AI / Design Discovery sprint is meant to surface anyway.