Four Questions to Ask Before You Hire an "Agentic AI" Team
Two teams can say the same sentence and mean systems years apart in maturity.
An agent loop, sometimes called an agentic loop, is the iterative cycle an AI agent uses to work toward a goal: observe, reason, act, verify, repeat until something observable changes. That's the mechanism behind most of what gets sold today as agentic AI. What's harder to find out, before you sign a contract, is whether the team telling you "we use agent loops" has actually built anything around that loop to make it trustworthy in production.
The distinction matters because the phrase itself has stopped meaning anything. McKinsey's 2025 State of AI survey found that 62% of organizations were at least experimenting with AI agents, while only 23% reported scaling an agentic AI system somewhere in the enterprise. Gartner went further in June 2025, predicting that over 40% of agentic AI projects will be scrapped by 2027. The reasons cited have nothing to do with the model: unclear value, rising cost, or inadequate risk controls. The label alone doesn't tell you which side of that gap a given team falls on.
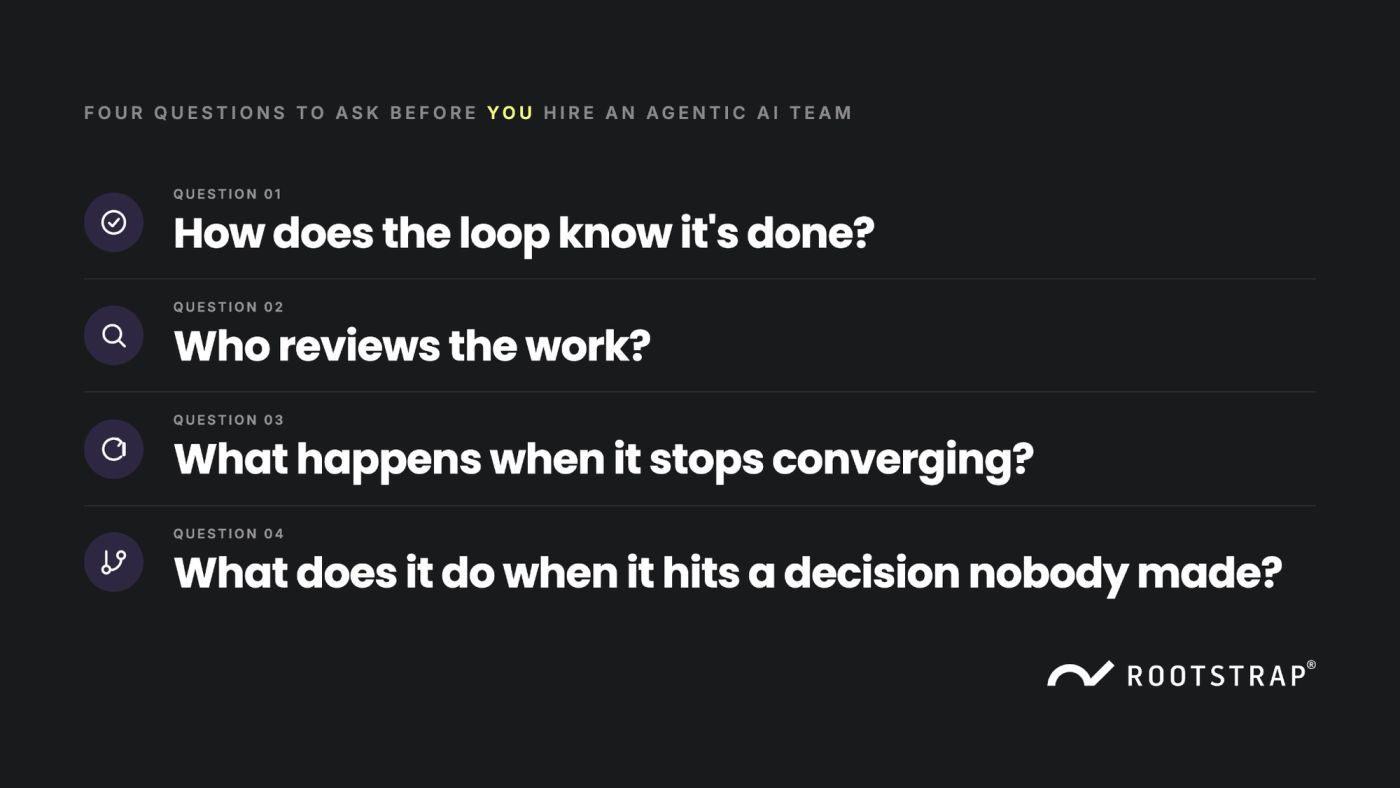
So instead of asking whether a partner or vendor uses agent loops, ask how their loop behaves at the four moments where agentic systems actually fail. The answers separate a system someone can operate from a demo someone can show you.
How does the loop know it's done?
A loop built for production exits on a condition someone can check independently: every acceptance criterion passed a review that wasn't done by the same agent that did the work. That's the answer to listen for. A loop that exits instead because an agent decided it was finished, or because it hit a fixed number of iterations, isn't verifying anything, it's guessing on a schedule. If a team can't describe their exit condition in one sentence, they haven't built one.
This is the part most demos skip, because it only shows up under real, messy requirements, not a scripted example.
Who reviews the work?
In a system with a genuine independent verification step, a person's review shifts from re-reading code to checking that the verification itself was sound. Were the right criteria checked, by an agent that didn't write the code under review? That's the shift that matters.
Every serious agentic system produces more output than a human can read line by line, so the honest answer is never "a person reviews everything." What matters is what the review is actually for. If the team's answer is a person "keeping an eye on it," ask what that person is looking at, and how they'd know if the loop had started producing convincing but wrong work.
What happens when it stops converging?
A mature system has a defined retry limit, what we call a bounce limit, where it stops retrying and hands the problem to a person, with enough context that the handoff is useful. That's what keeps iteration honest. Iteration itself is normal: a team that tells you their agents get it right on the first try every time isn't describing a loop, they're describing a script. In our 2026 production runs, roughly four in ten needed at least one additional pass, and about half of those needed a second.
Iteration isn't the problem. Iteration without a limit is. Ask what happens after the third, fifth, or tenth pass on the same issue. If the answer is "it keeps trying until it works," you're buying a system that can't tell the difference between being active and making progress. You'll find out the difference on your own dime. We wrote in detail about how we instrument and track agent-loop convergence.
What does it do when it hits a decision nobody made?
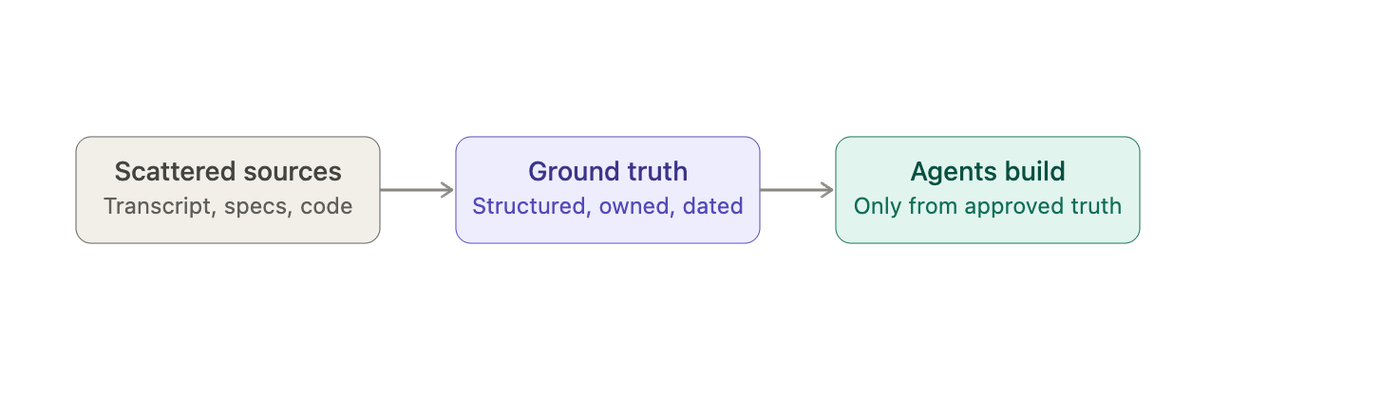
What a mature team should have in place is a living record of the decisions, constraints, and context specific to your project. It's built together with your team as the work progresses, and structured so agents can consult it directly instead of guessing. At Rootstrap we call this record Ground Truth. It's co-built with you, the client, and it's what an agent checks before escalating instead of retrying blindly. That's why the answer to "what happens when nobody made this decision yet" is "we ask you," not "we guess and hope it's close enough."
This is the question teams answer the worst, because it's the one that isn't really about the AI. Sometimes an agent loop stalls not because the code is wrong or the spec is unclear, but because the real blocker is a product decision nobody, human or agent, has made yet. It could be a policy question, a tradeoff the client hasn't weighed in on, or an assumption baked into the original brief that turned out to be wrong. A loop that keeps iterating on the spec when the missing piece is a decision one layer up will burn cycles without producing anything useful. So ask where your project's decisions are written down, and whether an agent can read them before it guesses.
One thing worth asking directly
If a team works across multiple clients, ask explicitly what travels between engagements and what doesn't. The mechanics that make a loop reliable, the escalation logic, the review gates, the bounce limits, are reusable. That reuse is part of why a team with more delivery experience should be faster than one starting from zero. What should never travel is anything specific to your project: your Ground Truth, your data, your product decisions. A team that can't draw that line clearly hasn't thought hard enough about either side of it.
If you're about to sign with an agentic AI partner and want a second opinion on their answers, write to us.
None of these four questions requires you to evaluate a model. They require the team to describe a system: how it knows it's done, who reviews the work, what happens when it stops converging, and what it does when it hits something no one, human or agent, has decided yet. Our own delivery system answers all four: a verifiable exit condition, an independent review pass, a defined limit before a run escalates to a person, and Ground Truth for the fourth. If you want the longer, more technical version, see how we instrument agent loops end to end. This piece is the one to hand to whoever in your organization has to decide whether to sign, not just whoever has to build with it.