As it became easier to generate content, the need for accurate classification became more important.
Software agents have become skilled at generating content. They can write diffs, explain plans, create labels for failures, and do so with confidence. However, they still struggle with the less visible but crucial task in every delivery process: figuring out what just happened and making sure it is handled the same way next time.
This is where Jev comes in, and why it is important alongside Rootshift.
What Jev actually is
Jev is not just another coding model. It does not write product code, design architecture, or fill in missing requirements. Instead, it acts as a System One evaluation layer. You send it structured data and specific questions—like choices, scores, or yes/no—and it quickly returns calibrated probabilities and confidence levels.
Jev’s role is intentionally focused. Tasks like failure triage, findings classification, completion checks, change-risk signals, context ranking, and limited judgment all follow the same pattern: classify, do not invent. Code-based policies then use confidence levels to decide whether to automate, review, or escalate. The main model still generates content, but Jev steps in first to check if that step is even needed.
What makes Jev impressive is not showiness, but consistency. It uses the same question formats, label sets, and thresholds every time. Instead of vague language from a generative model, you get clear fields that can be stored, combined, and audited.
Why that matters for delivery
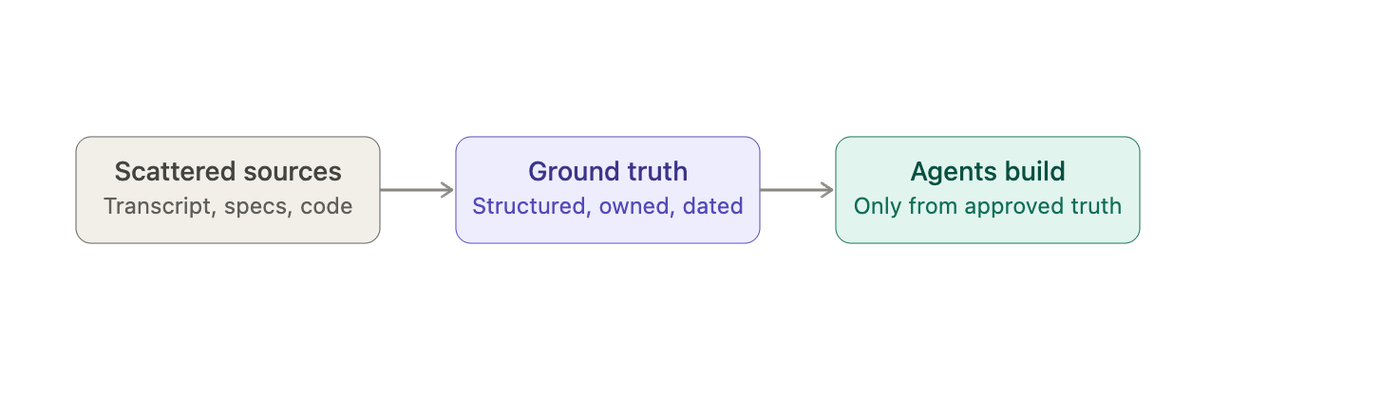
In AI-driven delivery, the challenge has shifted. Building things is now easy, but making accurate judgments is costly. We discussed this change when we recommended a shared Ground Truth: agents need a clear view of what is true, what has been verified, and what a human has approved.
Rootshift serves this purpose. It stores Ground Truth, gates, evidence, and a Delivery Pack that specialists use without making up new claims. It also keeps a record of facts: what was run, which commit it used, the exit code, cost, and method stamp.
Facts alone do not solve everything. Between a message like “the probe failed” and the decision to “retry with a heavier model,” there is a classification step. Teams often hide this step in prompts, and the wording can change over time. As a result, labels for capabilities may differ between runs, and telemetry ends up counting strings that do not always mean the same thing.
Jev stands out because it addresses this specific gap. It makes classification more like precise measurement.
Where Rootshift and Jev meet
We maintain a clear separation:
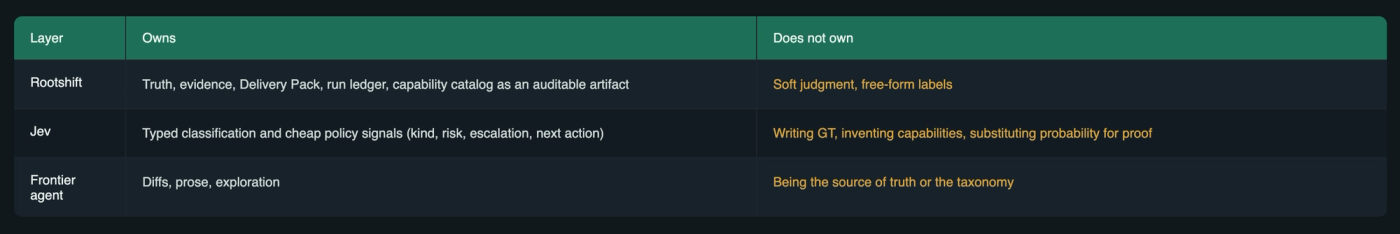
A comparison table separating Rootstrap's three delivery layers by responsibility: Rootshift owns truth, evidence, and the auditable capability catalog; Jev owns typed classification and policy signals like kind, risk, and escalation; the frontier agent owns diffs, prose, and exploration, but none of the three owns the others' territory.
This separation is how we use Jev together with Rootshift.
Capability classification and labels
Rootshift already organizes things by capabilities: probes, gates, fixtures, and surfaces that can be counted and displayed in a Record. The challenge is not storing them, but naming them. If a capability is just a path or a phrase created by the model, then yesterday’s “1,288 capabilities” and today’s “1,288 capabilities” might not refer to the same things.t.
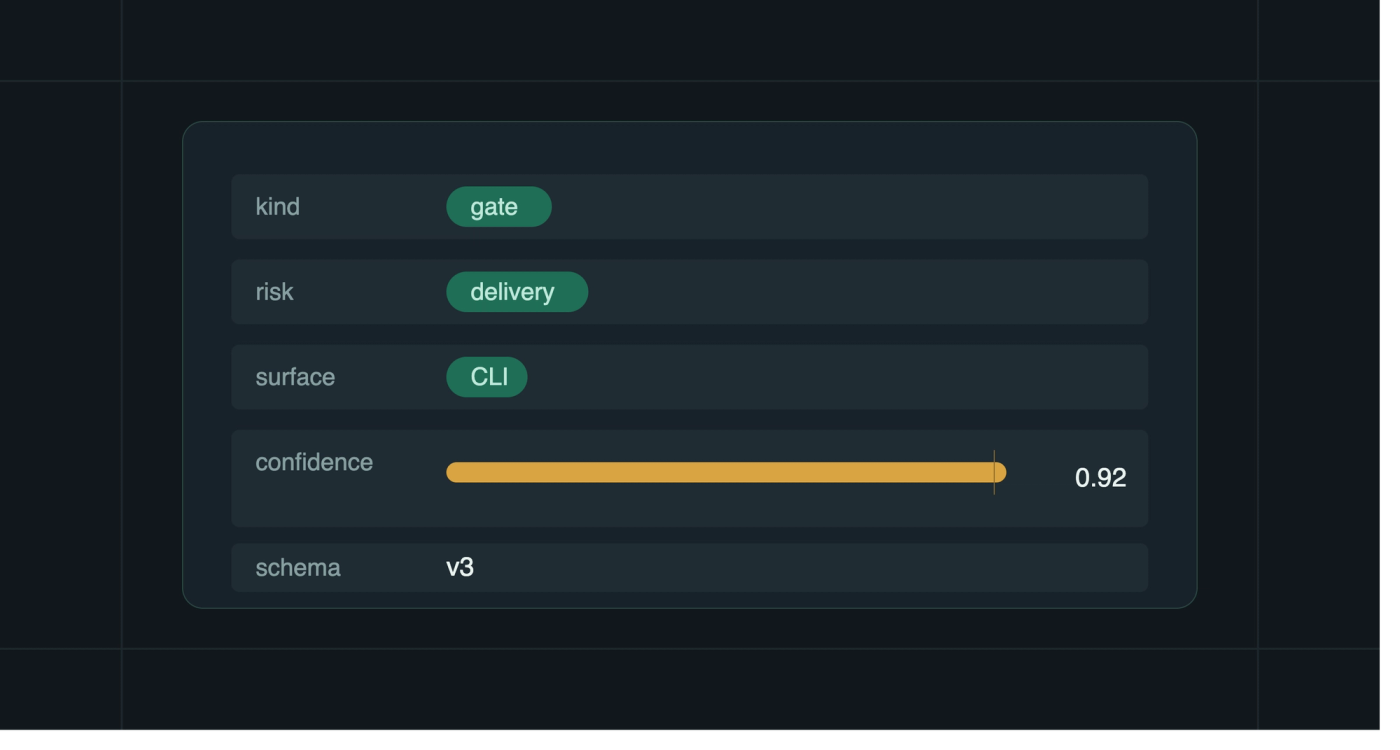
With Jev involved, each potential capability is classified using a fixed set of labels that are versioned in Rootshift (CapabilityLabelSet). Here are some example questions we focus on:
- What kind is this: gate, probe, fixture, sidecar, human signoff?
- What surface: CLI, API, UI, doc, estate?
- What risk class: truth, delivery, cost, safety?
- Is it covered by evidence: covered, partial, orphan?
Jev selects from these options. Rootshift saves the label, probabilities, confidence, schema version, and call ID. This way, the catalog remains a record of classified items, not just a collection of similar terms.
Findings and failures
When a gate or probe fails, a generative model tends to provide explanations. While these explanations are helpful later, the first priority is a stable triage: understanding the relationship, scope, and escalation. Jev’s failure and findings processes return likelihood signals instead of diagnoses. Rootshift records these details for each run. Only after that does the orchestrator decide whether to use the main model again, retry, or pause for human review.
This follows the same honesty rule we apply to the Delivery Pack: do not make up claims. Jev does not guess the root cause. Instead, it provides a ranked, specific guess that you can set thresholds for in code.
Telemetry: what to call, and why
We see telemetry as having two separate layers that should remain distinct:
- Fact telemetry (Rootshift): run.started, run.finished, exit, duration, tokens, method_commit, pack sha. These are actual events that took place.
- Decision telemetry (Jev): capability.classified, finding.normalized, gate.failure.triaged, next_action, claim.checked. These are judgments made using a fixed schema.
If Jev were called every time the ledger is updated, it would create unnecessary noise. The goal is to call it only for each classification or policy decision. Using a cache based on hashed state keeps repeated situations efficient and labels consistent. Outcomes can be added later, so calibration improves without changing past records.
The Record, or any public metric, remains accurate only if every number is based on a query that joins data by label schema version and date. This avoids using marketing numbers that lack proper classification.
Determinism, in the sense that shipping cares about
The goal is not to have identical probabilities at the bit level. Instead, we aim for operational consistency:
- closed label sets, versioned
- fixed question templates per stage
- thresholds in code (confidence ≥ τ → auto-apply; else review)
- ledger rows that store label + confidence + schema, not paragraph gloss
This approach makes an AI-driven delivery system auditable, even when agents are involved. Humans still make the tough decisions, while machines handle the routine ones without improvising.
Why this is impressive (without the hype)
Jev stands out because it avoids taking on the wrong tasks. While the market often values longer answers, Jev provides short, clear uncertainty. In a system with strong generators, it makes the decision layer easy to understand.
Rootshift is impressive for a different reason: it does not allow rendering specialists or chat sessions to become the source of truth. Together, Jev and Rootshift create a straightforward structure for our workflow:
Rootshift keeps track of what is true and what has been measured. Jev identifies what type of thing we believe it is, in a consistent and cost-effective way. Humans provide the final approval.
This is how we use Jev within the Rootshift delivery process: not as an extra writer, but as the classifier that keeps capabilities, failures, and next steps clear and consistent, instead of letting them become vague or inconsistent.